Hyperfence uses deterministic methods to move your AI from
probably
to provably safe
Attack surfaces
Where AI needs protection
A generative AI product is exposed at three points: what users send in, what it is
allowed to discuss, and what the model sends back.
01 / Input
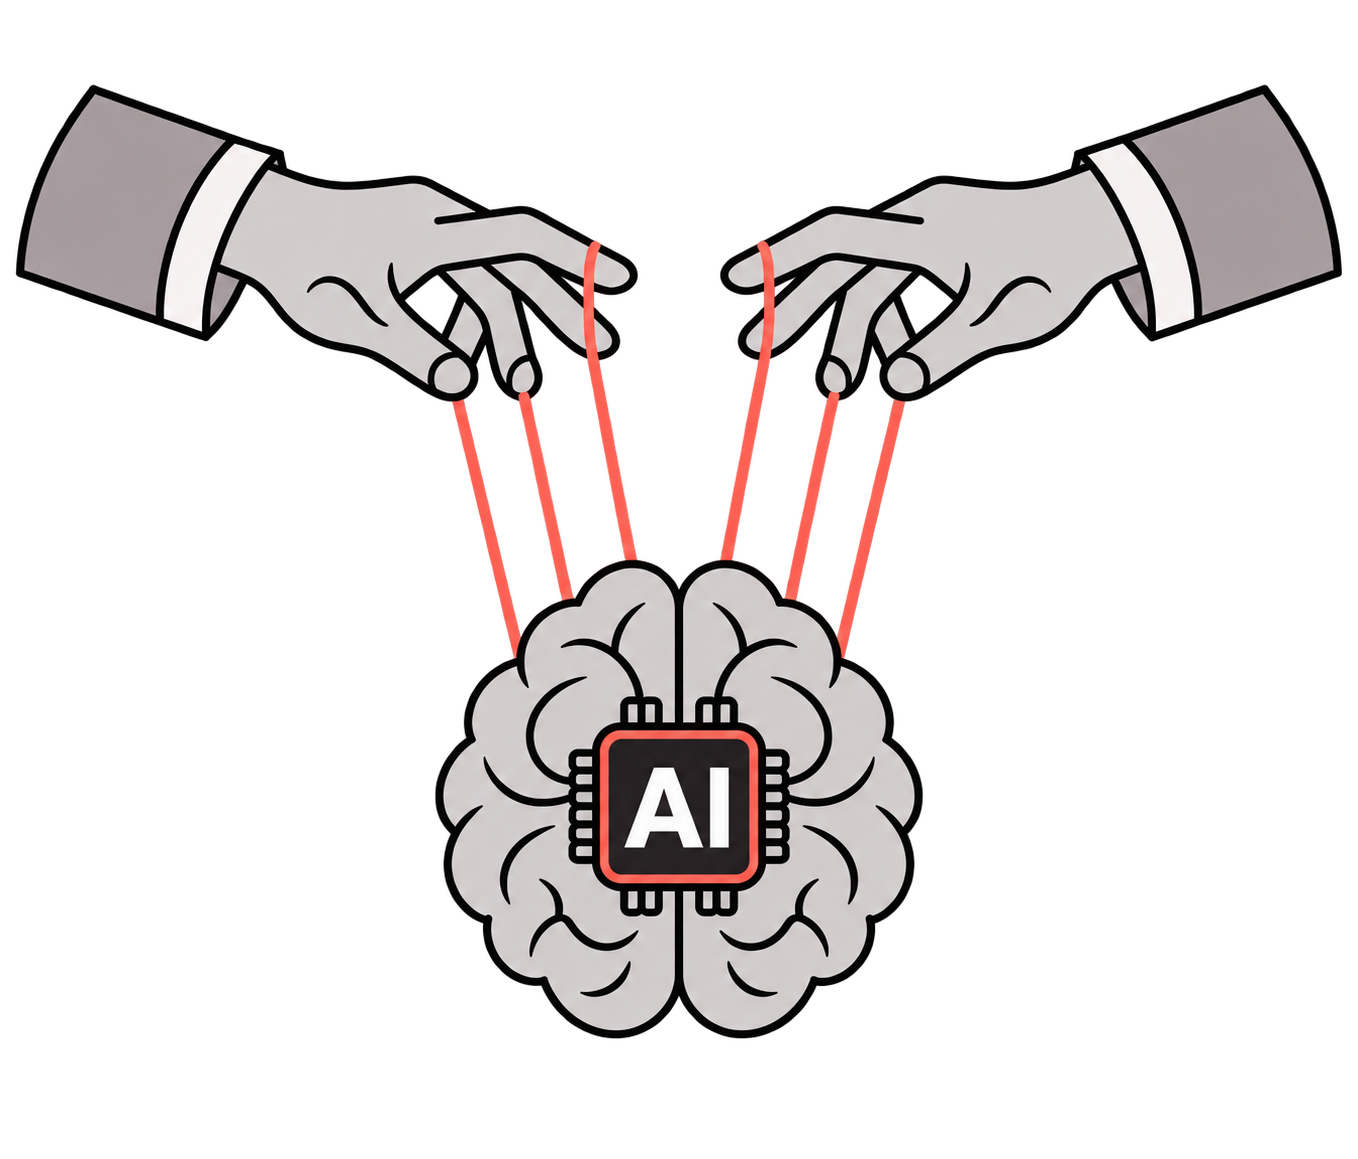
Users will try to manipulate your AI
Users craft messages designed to override your instructions, extract private data, or make your bot say things it should not.
Hyperfence blocks prompt injection and jailbreaks
Including attempts that disguise their intent rather than asking outright.
See covered attacksfor Users will try to manipulate your AI
✓Prompt injection
✓Jailbreaks
✓Disguised attacks
02 / Scope
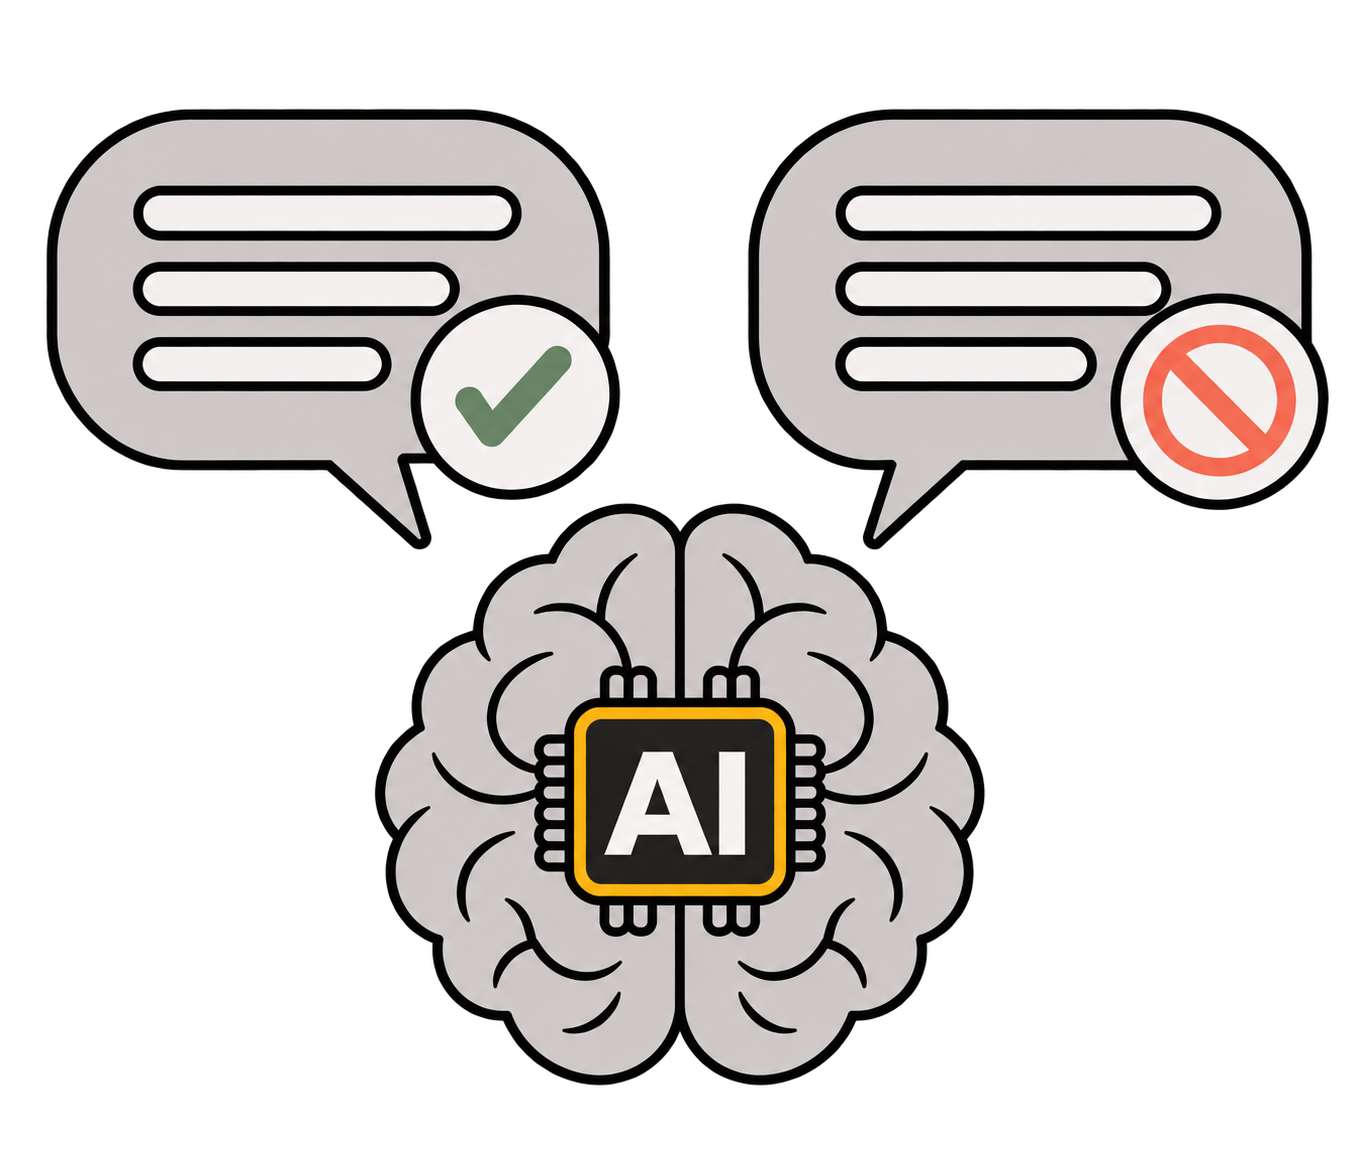
Every business has topics its AI should not discuss
A customer service bot discussing competitor pricing, a support bot drawn into a political debate. Generic content filters cannot know your rules.
Hyperfence keeps conversations within your rules
Custom Hyperfences take your rules and examples and turn them into boundaries that hold, even when users rephrase or switch language.
See scope examplesfor Every business has topics its AI should not discuss
✓Allowed and blocked topics specific to your business
✓Rules hold when users rephrase or switch language
✓No ML expertise needed - give rules and examples, we do the rest
03 / Output
What your model says back is your brand talking
One harmful, offensive or off-brand answer creates reputational and legal risk. Relying on the model to police itself is not enough.
Hyperfence doesn’t leave your brand to chance
Hyperfence applies deterministic controls before responses reach your users, catching risky content in milliseconds without asking another LLM to judge the output.
See output checksfor What your model says back is your brand talking
✓Built-in fences for common content risks
✓Checks what users send and what your model replies
✓Purpose-built classifiers - milliseconds, not a second LLM